LLM-as-a-Judge Reliability Auditor
2026-03
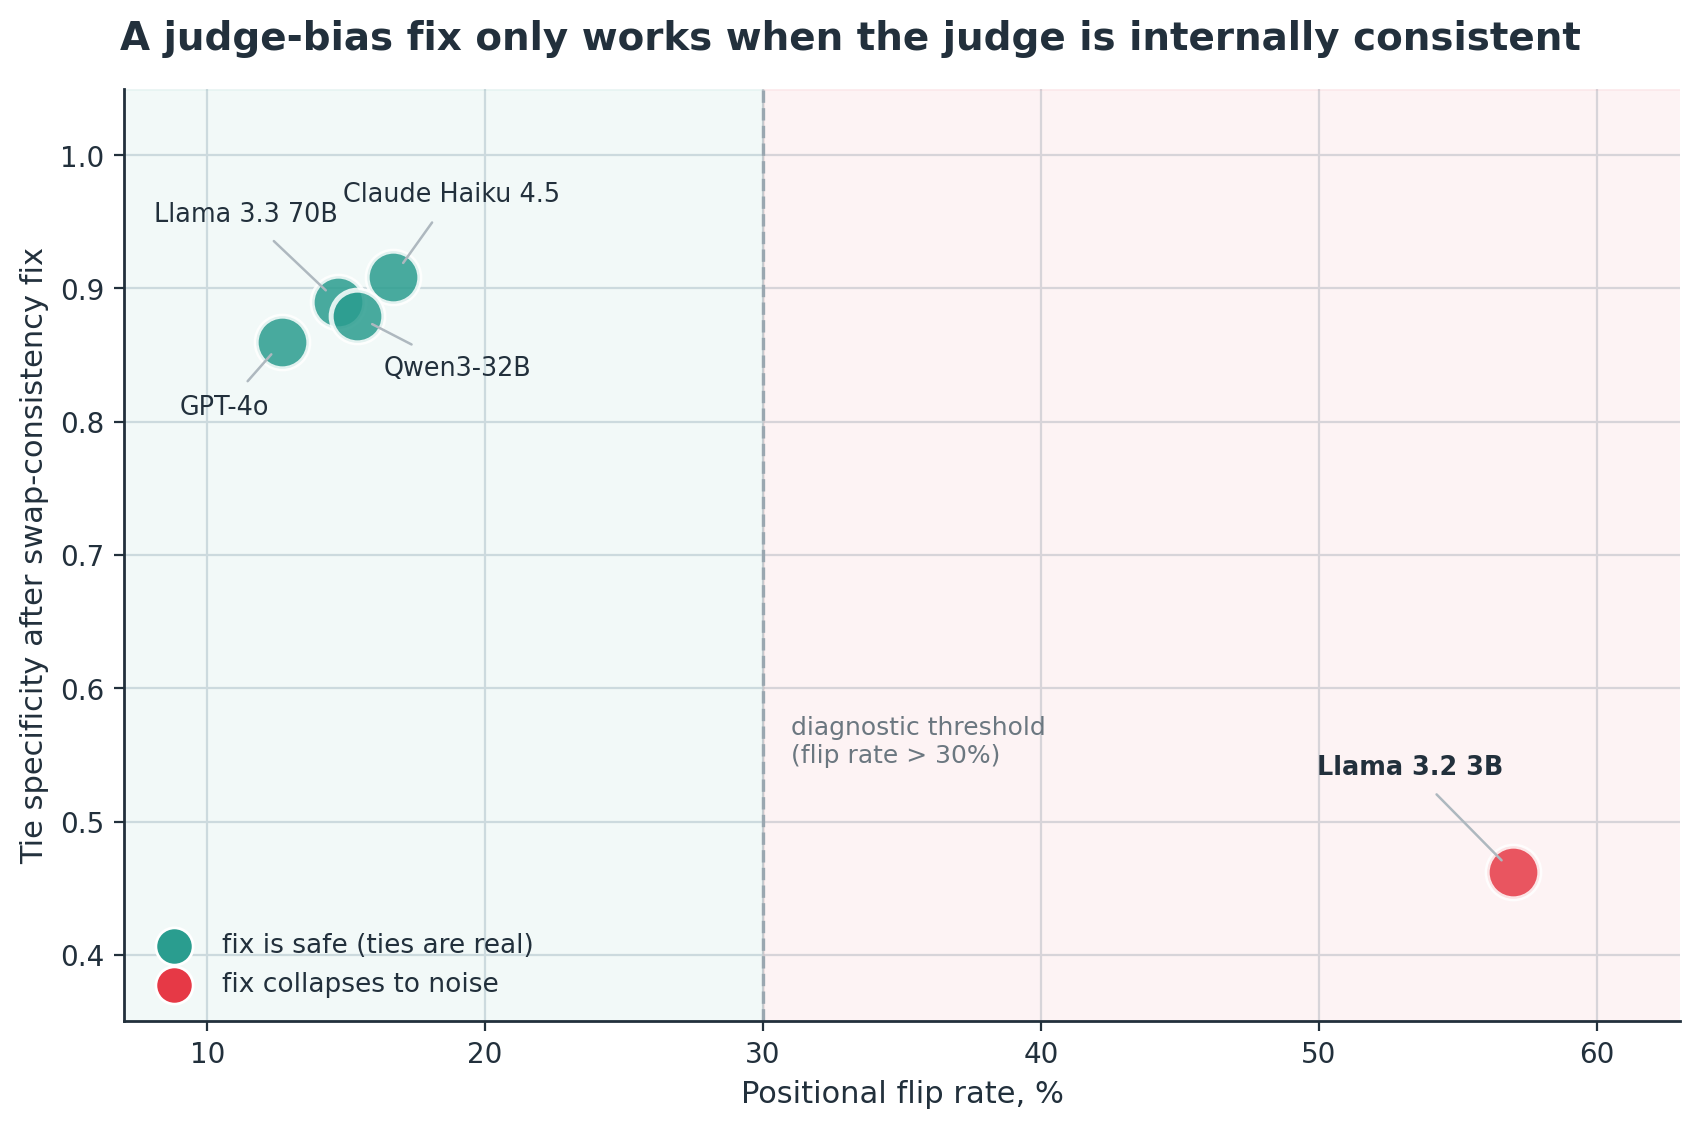
An end-to-end reliability audit of LLM-as-a-judge systems. Each judge evaluated pairs of model responses from MT-Bench, multiple biases were measured (verbosity, positional, model-family preference, self-preference, and human agreement), then modeled with cluster-robust logistic regression to account for non-independence in the data. A pre-registered calibration experiment fixed the one failure mode that could actually be corrected (tie under-calling), and the findings were re-tested on a second dataset (JudgeBench) to check whether they generalized. Across five judges (Claude Haiku 4.5, Llama 3.1 70B, GPT-4o, Qwen3-32B, Llama 3.2 3B), Claude Haiku 4.5 showed no verbosity bias once response quality was accounted for, while Llama 3.2 3B was severely vulnerable to padding and flipped its verdict on 57% of position swaps. A swap-consistency calibration (calling a tie when the A-first and B-first verdicts disagreed) was an effective structural fix for four of the five judges, but collapsed on Llama 3.2 3B because of its high noise floor.
- Dataset
- MT-Bench
- Models
- Claude Haiku 4.5, GPT-4o, Llama 3.1 70B, Llama 3.2 3B, Qwen3-32B
- Evaluation
- Positional, verbosity, self-preference, and human-disagreement bias, tie-detection rate
- Results & insight
- Swap-consistency calibration lifted tie-detection up to 4x, plus a three-test diagnostic that predicted which judges the fix was safe on